Tag Archives: r statistics

R Tutorial: Using R with NORC GSS Data Part Two, Generating Simple Tables and Using Subsets


A tutorial by Douglas M. Wiig

Part one of the tutorial  centered on importing NORC GSS data in STATA or SPSS formats in an R data frame. For illustration I used the GSS2014 survey data set that consists of 2538 cases and 866 variables. If a researcher wishes to generate some simple cross tabulations the R CrossTable function is very useful.

The CrossTable function is part of the gmodels package, so before running scripts in this tutorial make sure you have installed and loaded gmodels from your favorite CRAN mirror site. As discussed in part one of the tutorial load the GSS2014 dataset into the global environment using:

>require(foreign)

>Dataset <- read.spss(“E:/research/Documents/GSS2014.sav”,

use.value.labels=TRUE, max.value.labels=Inf, to.data.frame=TRUE)

The CrossTable function allows a basic cross tabulation to be performed and includes a large number of options that can be incorporated into the table. The basic structure is as follows:

Usage

CrossTable(x, y, digits=3, max.width = 5, expected=FALSE, prop.r=TRUE, prop.c=TRUE,

prop.t=TRUE, prop.chisq=TRUE, chisq = FALSE, fisher=FALSE, mcnemar=FALSE,

resid=FALSE, sresid=FALSE, asresid=FALSE,

missing.include=FALSE,

format=c(“SAS”,”SPSS”), dnn = NULL, …)

Arguments

x A vector or a matrix. If y is specified, x must be a vector

y A vector in a matrix or a dataframe

digits Number of digits after the decimal point for cell proportions

max.width In the case of a 1 x n table, the default will be to print the output horizontally.

If the number of columns exceeds max.width, the table will be wrapped for

each successive increment of max.width columns. If you want a single column

vertical table, set max.width to 1

expected If TRUE, chisq will be set to TRUE and expected cell counts from the _2 will be

included

prop.r If TRUE, row proportions will be included

prop.c If TRUE, column proportions will be included

prop.t If TRUE, table proportions will be included

prop.chisq If TRUE, chi-square contribution of each cell will be included

chisq If TRUE, the results of a chi-square test will be included

fisher If TRUE, the results of a Fisher Exact test will be included

mcnemar If TRUE, the results of a McNemar test will be included

resid If TRUE, residual (Pearson) will be included

sresid If TRUE, standardized residual will be included

asresid If TRUE, adjusted standardized residual will be included

missing.include

If TRUE, then remove any unused factor levels

format Either SAS (default) or SPSS, depending on the type of output desired.

dnn the names to be given to the dimensions in the result (the dimnames names).

optional arguments

(Gregory Warnes, maintainer, Package ‘Gmodels’ February, 2015. http://cran.r-project.org/src/contrib/PACKAGES.html)

In this tutorial I will create a  table to examine the relationship between income and education using the variables ‘degree’ and ‘income6’ from the GSS dataset. Both are categorical factors. To simplify the resulting table only actual frequencies will be reported and the ‘chisq’ option will be used to generate a chi-squared test. The format used will be set to SPSS. Use the following statement:

>Generate a cross table of frequencies with chisq reported

>CrossTable(Dataset$”incom16″,Dataset$”degree”, chisq=TRUE, format=c(“SPSS”),prop.r=FALSE, prop.c=FALSE, prop.t=FALSE, prop.chisq=FALSE)

>

In the above code, the row variable is income the appropriate column of the dataset is selected with the ‘Dataset$”incom16” statement. The column variable for the table is education and the appropriate column of the dataset is selected with the ‘Dataset$”degree” statement. The various cell proportions must be set to ‘FALSE’ as they are defaulted to ‘True.’

When you run the above script the table will be generated in SPSS format on the screen.  I will not reproduce the table here because of formatting problems of fitting the table into the blog format.

In part three of this turorial I will discuss generating subsets of the GSS data file and using subsets for statistical analyses such as t tests and ANOVA.


Using R in Nonparametric Statistical Analysis, The Kruskal-Wallis Test Part Three: Post Hoc Pairwise Multiple Comparison Analysis of Ranked Means


Using the Kruskal-Wallis Test, Part Three:  Post Hoc Pairwise Multiple Comparison Analysis of Ranked Means

A tutorial by Douglas M. Wiig

In previous tutorials I discussed an example of entering data into a data frame and performing a nonparametric Kruskal-Wallis test to determine if there were differences in the authoritarian scores of three different groups of educators. The test statistic indicated that at least one of the groups(group 1) was significantly different from the other two.

In order to explore the difference further it common practice to do post hoc analysis of the differences. There are a number of methods that have been devised to do these comparisons, but one of the most straightforward and easiest to understand is pairwise comparison of ranked means(or means if using standard ANOVA.)

Prior to entering the code for this section be sure that the following packages are installed and loaded:

       PMCMR

   prirmess

In part one data was entered into the R editor to create a data frame. Data frames can also be created directly using R script. The script to create the data frame for this example uses the following code:

#create data frame from script input

>Group <- c(1,1,1,1,1,2,2,2,2,2,3,3,3,3)

>authscore <-c(96,128,83,61,101,82,121,132,135,109,115,149,166,147)

>kruskal <- data.frame(Group, authscore)

The group identifiers are entered and assigned to the variable Group, and the authority scores are assigned to the variable authscore. Notice that each identifier is matched with an appropriate authscore just as they were when entered in columns using the data editor. The vectors are then assigned to the variable kruskal to create a data.frame. Once again the structure of the data frame can be checked using the command:

>str(kruskal)

resulting in:

'data.frame':   14 obs. of  2 variables:
 $ Group    : num  1 1 1 1 1 2 2 2 2 2 ...
 $ authscore: num  96 128 83 61 101 82 121 132 135 109 ...

>

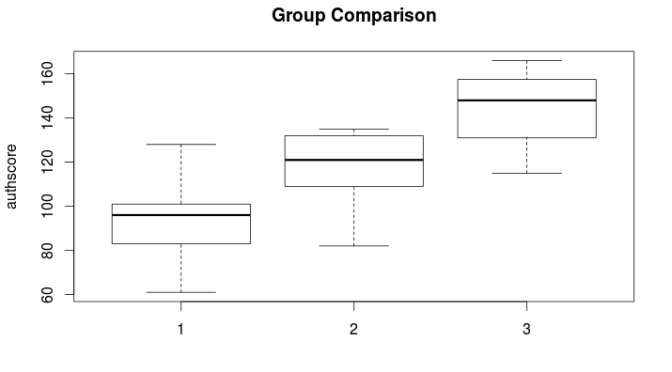
It is often useful to do a visual examination of the ranked means prior to post hoc analysis. This can be easily accomplished using a boxplot to display the 3 groups that are presented in the example. If the data frame created in tutorial one is still in the global environment the boxplot can be generated with the following script:

>#boxplot using authscore and group variables from the data frame created in part one

>boxplot(authscore ~ group, data=kruskal, main=”Group Comparison”, ylab=”authscore”)

>

The resulting boxplot is seen below:

Rplot5

As can be seen in the plot, authority score differences are the greatest between group 1 and 3 with group 2 In between. Use the following code to run the Kruskal-Wallis test and examine if any of the means are significantly different:

#library(PMCMR)

with(kruskal, {

posthoc.kruskal.nemenyi.test(authscore, Group, “Tukey”)

}

The post hoc test used in this example is from the recently released PMCMR R package. For details of this and other post hoc tests contained in the package( see Thorsten Polert, Calculate Pairwise Multiple Comparisons of Mean Rank Sums, 2015. http://cran.r-project.org/web/packages/PMCMR/PMCMR.pdf.) The test employed here used the Tukey method to make pairwise comparisons of the mean rank authoritarianism scores of the three groups. The output from the script above is:

Pairwise comparisons using Tukey and Kramer (Nemenyi) test

with Tukey-Dist approximation for independent samples

data: authscore and Group

      1                    2

2   0.493             –

3    0.031        0.310

P value adjustment method: none

The output above confirms what would be expected from observing the boxplot. The only means that differ significantly are means 1 and 3 with a p = .031.

The PMCMR package will only work with R versions 3.0.x. If using an earlier version of R another package can be used to accomplish the post hoc comparisons. This package is the pgirmess package (see http://cran.r-project.org/web/packages/pgirmess/pgirmess.pdf for complete details). Using the vectors authscore and Group that were created earlier the script for multiple comparison using the pgirmess package is:

library(pgirmess)

authscore <- c(96,128,83,61,101,82,121,132,135,109,115,149,166,147)

Group <- c(1,1,1,1,1,2,2,2,2,2,3,3,3,3)

kruskalmc(authscore ~ Group, probs=.05, cont=NULL)

and the output from this script using a significance level of p = .05 is:

Multiple comparison test after Kruskal-Wallis

p.value: 0.05

Comparisons

      obs.dif    critical.dif     difference

1-2    3.0        6.333875         FALSE

1-3    7.1        6.718089         TRUE

2-3    4.1        6.718089        FALSE

>

As noted earlier the comparison between groups one and three is shown to be the only significant difference at the p=.05 level.

Both the PMCMR and the pgirmess packages are useful in producing post hoc comparisons with the Kruskal-Wallis test. It hoped that the series of tutorials discussing nonparametric alternatives common parametric statistical tests has helped demonstrate the utility of these approaches in statistical analysis.

In part four I will post the complete script used in all three tutorials.

Using R for Nonparametric Statistics: The Kruskal-Wallis Test, Part Two


Using R for Nonparametric Statistics:  The Kruskal-Wallis Test, Part Two

A Tutorial by Douglas M. Wiig

Before we can run the Kruskal-Wallis test we need to define which column contains the factors (independent variables) and which contains the authoritarianism scores (dependent variable). Once we define the factor column R will match the correct score to each of the 14 observations.
As set up in the study, ‘Group’ is the factor(independent variable), and ‘authscore’ is the dependent variable. Use the command:

> Group <-factor(1,2,3)

This designates which observation belongs to each group. To make sure the data structure has been set up correctly use the command:

> str(kruskal)
‘data.frame’: 14 obs. of 2 variables:
$ Group : num 1 1 1 1 1 2 2 2 2 2 …
$ authscore: num 96 128 83 61 101 82 124 132 135 109 …
>

The output of this command shows a summary of the structure of the data frame created. We can now run the Kruskal Wallis test with the command:

> kruskal.test(authscore ~ Group, data=kruskal)

The output will be:

Kruskal-Wallis rank sum test

data: authscore by Group
Kruskal-Wallis chi-squared = 6.4057, df = 2, p-value = 0.04065

>

As seen in the above output the analysis of authoritarianism score by group indicates that the probability of differences in scores among the three groups being due to chance alone is less that the .05 alpha level that was set for the study. (pobt < .05). Further post hoc analysis would be necessary to determine the exact nature of the differences among the scores of the three groups. This will be the topic of a future tutorial.

More to come:  Part Three will explore the use of multiple comparison techniques to analyze ranked means

Using R for Nonparametric Analysis: The Kruskal-Wallis Test, Part One


Using R for Nonparametric Data Analysis: The Kruskal-Wallis Test

A tutorial by Douglas M. Wiig

Analysis of variance(ANOVA) is a commonly used technique for examining the effect of an independent variable on three or more dependent variables. There are several types of ANOVA ranging from simple one-way ANOVA to the more complex multiple analysis of variance, MANOVA. ANOVA makes several assumptions about the sample data being used such as the assumption of normal distribution of the variables in the parent population, underlying continuous distribution of the variables, and interval or ratio level measurement of all variables. If any of these assumptions cannot be met a researcher can turn to a nonparametric counterpart to ANOVA for the analysis. This tutorial will discuss the use of the Kruskal-Wallis test, the nonparametric counterpart to analysis of variance.

In this tutorial I will explore a simple example and discuss entering the sample data into a data file using the R data editor. I will then discuss setting up the data for analysis and using the Kruskal-Wallis test.

I am going to assume that the reader has a working knowledge of ANOVA with parametric data. Since ANOVA uses sample means and variances as the basis of the statistical test interval or ratio level measurement is necessary to insure valid results in addition to the assumptions indicated above. With the nonparametric Kruskal-Wallis test the only assumptions to be met are ordinal or better measurement and the assumption of an underlying continuous measurement. The example to be used here is taken from a book on nonparametric statistics by Sidney Seigel.(Sidney Seigel, Nonparametric Statistics for the Behavioral Sciences, New York: McGraw-Hill, 1956, pp-184-196).

A researcher wishes to test the hypothesis that school administrators are typically more authoritarian than classroom teachers. He also believes that many classroom teachers are adminstration-oriented in their professional aspirations which may, in turn, have an effect on their authoritarianism. 14 subjects are selected and divided into three groups: teaching-oriented teachers (classroom teachers who wish to remain in a teaching position), administration-oriented teachers (classroom teachers who aspire to become administrators), and practicing administrators.(Seigel, p. 186). The level of authoritarianism of each subject is measured through a survey that assigns an authoritarianism score that is considered to be at least ordinal in nature. Higher scores indicate higher levels of authoritarianism. (Siegel, p. 186). The null hypothesis is that there is no difference in mean authoritarianism scores among the three groups. The alternative hypothesis is that the mean authoritarianism scores among the three groups are different. The alpha level for rejecting the null hypothesis is p = .05. (Seigel, p. 186).

Since we make no assumption about a normal distribution of scores, have a small sample size of n = 14, and ordinal measure we will use the nonparametric test which is based on median scores and ranks rather than means and variances as used in parametric ANOVA. The mathematical details of how this is done is beyond the scope of this tutorial. See Seigel, p. 187-189 for details. The authoritarian scores for the three groups are shown below:

Authoritarianism Scores of Three Groups of Educators

Teacher-Oriented        Admin-oriented    Administrators

teachers   n=5                teachers   n=5                n=4

—————————————————————————————-

96                                  82                               115

128                              124                               149

83                               132                               166

61                               123                               147

101                             109

—————————————————————————————-

(Seigel, p. 187)

The first task is to create an R data frame with the scores from the table. We will enter the scores using the R data editor. We will name the data frame ‘kruskal.’   Invoke the editor using the following commands:

  > kruskal <- data.frame()

   > kruskal <- edit(kruskal)

You should see the data entry editor open in a separate window. In order to process the data properly it needs to be entered into two columns. The first column will be the factors (which group the scores belong to), and the second column will contain the actual scores. Label column 1 ‘Group’ and column 2 ‘authscore.’ When the data are entered your editor should look like this:

———————-

Group  authscore

1    1               96

2    1            128

3    1             83

4    1            61

5    1           101

6    2            82

7    2           121

8    2          132

9    2          135

10   2       109

11   3       115

12   3       149

13   3       166

14   3       147

———————-

Make sure that each column of numbers is of the data type “Real.” l Close the data editor by clicking ‘Quit’ and the data will be saved in the working directory for access. To see what has been entered in the data editor use the command:

> kruskal

Group authscore

1     1             96

2     1            128

3     1             83

4     1            61

5     1           101

6     2            82

7     2           121

8     2            132

9     2            135

10     2         109

11     3         115

12     3         149

13     3         166

>

You should see the output as above. If you need to make changes simple invoke the editor with:

> kruskal <-edit(kruskal)

The editor will open and you can make any changes you need to. Be sure to click on ‘Quit’ to save the changes to the working directory.

Part Two will continue the analysis

Book Review: R High Performance Programming


A book review by Douglas M. Wiig

Aloysius Lim and William Tjhi. R High Performance Programming. Birmingham, UK: Packt Publishing Ltd., 2015. bit.ly/14Rhpp

R High Performance Programming is a well written, informative book most suited for the experienced R programmer. This book offers a handy guide for R users who need speed and efficiency for the tasks that they perform.

The authors begin with an informative chapter discussing some of the inherent constraints on R’s computing performance such as CPU and RAM usage, and how R code is interpreted on the fly rather than compiled. A guide to several methods of profiling R’s code execution time, memory allocation and CPU usage is discussed in the next chapter. Sample code included in the chapter allows the reader to experiment with various benchmarking techniques to measure processing time and memory usage. This chapter provides the reader with some good tools for benchmarking R projects and identifying areas where improvements in processing can be made.

As is always the case with technical books from Packt Publishing, ample code examples are used in the chapter and the complete code used in each chapter is available for download with the book. This is a very handy feature and allows readers to do some live programming with R as the book is read.

The authors discuss a number of simple tweaks that can be easily performed to increase processing speed such as using built in functions and using hash tables. The hash table technique is useful for applications that use frequent lookups and can dramatically reduce processing time when compared to the use of lists. Running example code using this technique shows a large decrease in processing time when using the hash table approach as compared to straight list processing lookups.

In chapter 4 the authors discuss the use of compiled R code and integrating compiled languages into R code. They show several examples of using the R package inline that allows users to embed C, C++, Objective-C, Objective-C++ and Fortran code within R. Once again there are ample code examples to illustrate the use of this technique. For more advanced uses of compiled code the authors discuss how to create entire modules coded in C++ using the Rcpp package. Several completed code examples are included to illustrate the technique.

Another interesting approach to speeding up R is discussed in a chapter that explores several R packages designed to exploit the capability of GPU’s (Graphic Processing Cards) that are a used in many computers. These techniques can facilitate creating very fast and efficient statistical modeling code using R and the GPU.

As indicated above, readers can download the code package included with the book and find a well-organized set of ten folders (one for each chapter) containing 51 files. These files contain the sample code from the book as well as other code segments and benchmark code discussed in the book. The authors indicate that the code has been tested on R 3.1.1, Ubuntu 14.04 Trusty Tahr, Mac OS X 10.9 Mavericks, and Windows 8.1. This allows integration of these code segments into the reader’s own projects with minimal changes.

Other chapters in R High Performance Programming discuss simple tweaks to use less memory, techniques to speed processing of large datasets and using parallel processing and clustering techniques. The last chapter contains a discussion of using R and Hadoop to process Big Data (massive datasets with sizes measured in petabytes -one petabyes is 1,048,576 gigabytes). Processing data of this magnitude presents many challenges and is an area that is currently the subject of much program development.

I found R High Performance Programming to be a useful and informative book for the advanced user of R. A working knowledge of statistics, R and other programming languages such as C++ or Java is necessary to realize the full benefit of the techniques presented in the book. The book also serves as a good learning tool for less knowledgeable R users who are seeking to advance their programming skills.

Readers who are interested in the use of Hadoop and cluster computer processing might find the book Raspberry Pi Super Cluster by Andrew K. Dennis of interest. (Packt Publishing, 2013

PAC-14-1987838-1387169). A review of this book can be found on my web site at http://dmwiig.net.

Reviewer Information:

Douglas M. Wiig, Professor of Political Science

Grand View University

Teaching areas include social science statistics and research methods, comparative politics, international politics.

Long time user and developer of computer and statistical applications

Host of Open Source Technology in Higher Education web site at http://dmwiig.net

Creator and moderator of LinkedIn discussion forum “Open Source Technology in Higher Education”

Regular contributor to several LinkedIn discussion forums

Author of numerous tutorials on using the R statistical programming language and Raspberry Pi computer

Using R for Basic Cross Tabulation Analysis: Part Three, Using the xtabs Function


Using R to Work with GSS Survey Data Part Three: Using xtabs to Create and Analyze Tables

A tutorial by D. M. Wiig
In Part Two of this series of tutorials I discussed how to find and import a data set from the NORC GSS survey. The focus of that tutorial was on the GSS2010 data set that was imported into the R workspace in SPSS format and then loaded into an R data frame for analysis.

Use the following code to load the data set into an R workspace:

>install.packages(“Hmisc”) #need for file import
>install.packages(“foreign”) #need for file import
>#get spss gss file and put into data frame
>library(Hmisc)
>gssdataframe <- spss.get(“/path-to-your-file/GSS2010.sav”, use.value.labels=TRUE)

The xtabs function provides a quick way to generate and view a cross tabulation of two variables and allows the user to specify one or more control variables in the cross tabulation. Using the variables “ partyid” and “polviews” the cross tablulation is generated with:

>#use xtabs to produce a table
>gsstab <- xtabs(~ partyid + polviews, data=gssdataframe)

To view the resulting table use:

>gsstab #show table

To view summary statistics generated use:

summary(gsstab)

This summary shows the number of cases in the table, the number of factors and the Chi-square value for the table.

Variables used in social science research are often interrelated so it is desirable to control for one or more variables in order to further examine the variables of interest. The table created in the gsstab data frame shows the relationship between political ideology and political party affiliation. To look at the relationship by gender use the following:

>#use xtabs to produce a table with a control variable
>gsstab2 <- xtabs(~ partyid + polviews+ sex, data=gssdataframe)

To view the new table use:

>gsstab2

To view summary statistics for the table enter:

>summary(gsstab2)

As noted above xtabs is a quick and powerful function to create N x N tables with or without control variables. In the next tutorial I explore the use of the ca function to produce a basic Correspondence analysis of underlying dimensions in an N x N table.

Using R to Work with GSS Survey Data: Cross Tabulation Tables


Using R to Work with GSS Survey Data: Viewing Datasets and Performing Cross Tabulations

A tutorial by D. M. Wiig

In a previous tutorial I discussed how to import datasets from the NORC General Social Science Survey using R to write the SPSS formatted data to an R data frame. Once the data has been imported into the R working environment it can be viewed and analyzed. There is a wealth of survey research data available at the NORC web site located at www.norc.org. In this tutorial the dataset gss2010.sav will be used. The dataset is available from www3.norc.org/GSS+Website.

From that page click on the “Quick Downloads” link on the right hand side of the page to access the list of available datasets. From the next page choose SPSS to access ‘.sav’ format files and finally “2010” under the heading “GSS 1972-2012 Release 6.” Please note that this is a rather large data file with 2044 observations of 794 variables. Download the file to a directory that you can access from your R console.

As discussed in a previous tutorial the SPSS format file can be loaded into an R data frame. Make sure that the R packages Hmisc and foreign have been installed and loaded before attempting to import the SPSS file. The following code will load the ‘.sav’ file:

>install.packages(“Hmisc”) #need for file import

>install.packages(“foreign”) #need for file import

>#get spss gss file and put into data frame

>library(Hmisc)

>gssdataframe <- spss.get(“/path-to-your-file/GSS2010.sav”, use.value.labels=TRUE)

Once the file is read into an R data frame it can be viewed in a spreadsheet like interface by using the command:

>View(gssdataframe)

Using the arrow keys, the home key, end key, and the page up and page down keys allows navigating and browsing the file.

Survey data such as that found in the GSS file is usually a mixture of data types ranging from ratio level numbers to categorical data. Cross tabulations are often used to explore relationships among variables that are ordinal or categorical in nature. R has a number of functions available for cross tabulations. The Table function is a quick way to generate a cross tabulation table with a number of options available. The following results in a frequency table of the variables “partyid” and “polviews” both of which are measured in categories:

>#use the gssdataframe

>#the variables partyid and polviews are used

>attach(gssdataframe)

>#create a table named ‘gsstable’

>gsstable <- table(partyid, polviews)

>gsstable #print table frequencies

The following output results:

                   polviews
partyid              EXTREMELY LIBERAL LIBERAL SLIGHTLY LIBERAL MODERATE
  STRONG DEMOCRAT                   41     105               42       94
  NOT STR DEMOCRAT                  14      62               57      154
  IND,NEAR DEM                      11      47               57      103
  INDEPENDENT                        5      20               33      189
  IND,NEAR REP                       1       4               16       74
  NOT STR REPUBLICAN                 2      10               16       88
  STRONG REPUBLICAN                  0       5                5       22
  OTHER PARTY                        1       5                6       16
                    polviews
partyid              SLGHTLY CONSERVATIVE CONSERVATIVE EXTRMLY CONSERVATIVE
  STRONG DEMOCRAT                      22           25                    6
  NOT STR DEMOCRAT                     28           16                    7
  IND,NEAR DEM                         25           11                    5
  INDEPENDENT                          43           32                    9
  IND,NEAR REP                         49           43                    8
  NOT STR REPUBLICAN                   72           72                   13
  STRONG REPUBLICAN                    23          101                   27
  OTHER PARTY                           3           12                    4

>

There are options available with the Table function that include calculating row and column marginal totals as well a cell percentages. Another quick method to generate tables is with the CrossTable function. The function is contained in the gmodels package and can be used on the table generated with the Table function above. Use the following lines of code to generate a cross table between ‘polviews’ and ‘partyid’ using the gsstable created above:

>library(gmodels)

>#produce basic crosstabs

>CrossTable(gsstable,prop.t=FALSE,prop.r=FALSE,prop.c=FALSE,chisq=TRUE,format=c(“SPSS”))

>

Cell Contents
|-------------------------|
|                   Count |
| Chi-square contribution |
|-------------------------|

Total Observations in Table:  1961 

                   | polviews 
           partyid |    EXTREMELY LIBERAL  |              LIBERAL  |     SLIGHTLY LIBERAL  |             MODERATE  | SLGHTLY CONSERVATIVE  |         CONSERVATIVE  | EXTRMLY CONSERVATIVE  |            Row Total | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
   STRONG DEMOCRAT |                  41  |                 105  |                  42  |                  94  |                  22  |                  25  |                   6  |                 335  | 
                   |              62.014  |              84.219  |               0.141  |               8.312  |              11.962  |              15.026  |               4.163  |                      | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
  NOT STR DEMOCRAT |                  14  |                  62  |                  57  |                 154  |                  28  |                  16  |                   7  |                 338  | 
                   |               0.089  |               6.911  |               7.238  |               5.486  |               6.840  |              26.537  |               3.215  |                      | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
      IND,NEAR DEM |                  11  |                  47  |                  57  |                 103  |                  25  |                  11  |                   5  |                 259  | 
                   |               0.121  |               4.902  |              22.674  |               0.284  |               2.857  |              22.144  |               2.830  |                      | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
       INDEPENDENT |                   5  |                  20  |                  33  |                 189  |                  43  |                  32  |                   9  |                 331  | 
                   |               4.634  |              12.733  |               0.969  |              32.889  |               0.067  |               8.107  |               1.409  |                      | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
      IND,NEAR REP |                   1  |                   4  |                  16  |                  74  |                  49  |                  43  |                   8  |                 195  | 
                   |               5.592  |              18.279  |               2.167  |               0.002  |              19.466  |               4.622  |               0.003  |                      | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
NOT STR REPUBLICAN |                   2  |                  10  |                  16  |                  88  |                  72  |                  72  |                  13  |                 273  | 
                   |               6.824  |              18.702  |               8.224  |               2.190  |              33.411  |              18.786  |               0.364  |                      | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
 STRONG REPUBLICAN |                   0  |                   5  |                   5  |                  22  |                  23  |                 101  |                  27  |                 183  | 
                   |               6.999  |              15.115  |              12.805  |              32.065  |               0.121  |             177.476  |              52.256  |                      | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
       OTHER PARTY |                   1  |                   5  |                   6  |                  16  |                   3  |                  12  |                   4  |                  47  | 
                   |               0.354  |               0.227  |               0.035  |               0.170  |               1.768  |               2.735  |               2.344  |                      | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|
      Column Total |                  75  |                 258  |                 232  |                 740  |                 265  |                 312  |                  79  |                1961  | 
-------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|----------------------|

 
Statistics for All Table Factors


Pearson's Chi-squared test 
------------------------------------------------------------
Chi^2 =  801.8746     d.f. =  42     p =  3.738705e-141 


       Minimum expected frequency: 1.797552 
Cells with Expected Frequency < 5: 2 of 56 (3.571429%)

Warning message:
In chisq.test(t, correct = FALSE, ...) :
  Chi-squared approximation may be incorrect

>

This code produces a table of frequencies along with a basic Ch-squared test. Other options include generating cell percentages and using either SPSS or SAS table format. This is accomplished by changing the appropriate flag from FALSE to TRUE and specifying either SPSS or SAS for the format flag. The table formatting is compressed in this example due to the narrow margin requirements of the web page.  Use the scroll bar at the bottom of the page to view the entire table.

There are many functions available in R to analyze data in tabular format. In my next tutorial I will examine using the xtabs function to produce basic cross tabulation with control variables.

R Tutorial: Using R to Work With Datasets From the NORC General Social Science Survey


R Tutorial: Using R to Work With Datasets From the NORC General Social Science Survey

A tutorial by D. M. Wiig

Part One:

When I teach classes in social science statistics and social science research methods I like to use “live” data as much as possible both in classroom lectures and in homework assignments. For the social sciences one excellent and readily available source of live data is the ongoing General Social Science Survey project, The National Data Program for the Sciences. This is a project of NORC, a National Science Research Center at the University of Chicago (see www.norc.org for the projects main web site.)

There a a number of datasets available in different formats. The quick download datasets that I like to use are primarily SPSS data files. Many institutions have SPSS available for students and faculty but the use of SPSS is my no means universal. I have found that it is easy to use R to read the .sav format files into an R data frame and then write the file out to a comma separated value, .csv format that can be read my almost any statistics software package. As I will discuss in this an future tutorials it is also quite effective to use R to analyze the GSS files.

To create R datasets using the GSS files we can use some of the file import/export features available in R. To begin, make sure that the R packages “Hmisc” and “foreign” are installed and loaded in your R session environment. This can be accomplished using:

> install.packages(“Hmisc”) #need for file import

> install.packages(“foreign”) #need for file import

As an example, the following code will load the GSS data file “gss2010x.sav” into an R data frame using the spss.get function:

>library(Hmisc)

>gssdataframe <- spss.get(“/path-to-your-file/gss2010x.sav”, use.value.labels=TRUE)

The file “gss2010x.sav” contains 500 observations of 47 variables. Codebooks and other information about the data in these datasets is readily avaiable for download from the NORC web site. After the data is loaded into the data frame it can be viewed using:

>gssdataframe

To convert and save the file to a comma separated value (.csv) format use the following use the write.table function:

>#write dataframe to .csv file

>write.table(gssdataframe, “/path-to-your-file/gss2010x.csv”,sep=”,”)

The file, now in a .csv format can be accessed with virtually any statistics package or other software. In my next tutorial I will discuss working with GSS data using the various table and cross table functions available in R.


How To: Download and install the latest version or R on your Linux Ubuntu OS


How To: Download and install the latest version or R on your Linux Ubuntu OS

(A Tutorial by D.M. Wiig)

I have several computers that use Linux operating systems and I have installed R on all of them. I use Debian on some of the machines and Ubuntu on others. When downloading R using the distribution’s package manager or from the command line I have notice that I will get versions of R ranging from 2.13.xx to 2.15.xxx depending on the Linux distribution. That has not been a problem until the release of the current version of R, version 3.0.3. Since this version is not backwards compatible with earlier releases it is necessary to upgrade to the new version to take advantage of new packages that are rapidly being developed as well as modification to existing packages to accommodate R 3.0.3. This tutorial will cover the installation of R 3.0.3 on the Ubuntu distribution of Linux.

When installing R 3.0.3 it is necessary to make sure that the current binaries are installed to your version of the Linux OS. If you are running a Ubuntu distribution you can edit the sources.list file on your computer to access the most up to date CRANs. Open a terminal program and enter the following from the command line:

$ cd /etc/apt/

$ dir

Make sure the file sources.list is in the directory and then edit the file opening the nano editor:

$ sudo nano sources.list

You should see a file in the editor that is similar to the file shown below:

—————————————————————————————————-

deb cdrom:[Kubuntu 11.10 _Oneiric Ocelot_ – Release i386 (20111012)]/ oneiric main restricted

deb http://streaming.stat.iastate.edu/CRAN/bin/linux/ubuntu precise/

# See http://help.ubuntu.com/community/UpgradeNotes for how to upgrade to

# newer versions of the distribution.

deb http://us.archive.ubuntu.com/ubuntu/ precise main restricted

deb-src http://us.archive.ubuntu.com/ubuntu/ precise main restricted

## Major bug fix updates produced after the final release of the

## distribution.

deb http://us.archive.ubuntu.com/ubuntu/ precise-updates main restricted

deb-src http://us.archive.ubuntu.com/ubuntu/ precise-updates main restricted

## N.B. software from this repository is ENTIRELY UNSUPPORTED by the Ubuntu

## team. Also, please note that software in universe WILL NOT receive any

## review or updates from the Ubuntu security team.

deb http://us.archive.ubuntu.com/ubuntu/ precise universe

deb-src http://us.archive.ubuntu.com/ubuntu/ precise universe

deb http://us.archive.ubuntu.com/ubuntu/ precise-updates universe

deb-src http://us.archive.ubuntu.com/ubuntu/ precise-updates universe

## N.B. software from this repository is ENTIRELY UNSUPPORTED by the Ubuntu

^G Get Help ^O WriteOut ^R Read File ^Y Prev Page ^K Cut Text ^C Cur Pos

^X Exit ^J Justify ^W Where Is ^V Next Page ^U UnCut Text ^T To Spell

—————————————————————————

I have highlighted the line that I added to this file. This line will force Linux to access the CRAN for the latest version of R in a library that is not normally searched for updates if you have an earlier version of R installed. For an Ubuntu distribution change the line to one of the following depending on the distribution that you have installed:

http://<myfavorite-cran-mirror&gt; /bin/linux/ubuntu saucy/

http://<myfavorite-cran-mirror&gt; /bin/linux/ubuntu quantal/

http://<myfavorite-cran-mirror&gt; /bin/linux/ubuntu precise/

http://<myfavorite-cran-mirror&gt; /bin/linux/ubuntu lucid/

Replace <myfavorite-cran-mirror> with the CRAN repository of your choice found at the web site http://cran.r.project.org/mirrors.html. In my case as shown above I used a CRAN repository here in Iowa at Iowa State University. Once the line has been entered in your sources.list file press ctrl-o to save the file, and press ctrl-x to exit the editor. Be sure when you invoke nano that you have root privileges (by using sudo nano) or you will not be able to write out the modified file.

Once you have successfully modified the sources.list file proceed with the R 3.0.3 installation by issuing the command:

$ sudo apt-get update (to make sure all supporting files are current)

and then:

$ sudo apt-get install r-base

When the update runs you should see that R 3.0.x is downloaded and is being installed. After the installation is complete test it by issuing the command:

$ R

You will see the output as shown below:

———————————————

R version 3.0.3 (2014-03-06) — “Warm Puppy”

Copyright (C) 2014 The R Foundation for Statistical Computing

Platform: i686-pc-linux-gnu (32-bit)

R is free software and comes with ABSOLUTELY NO WARRANTY.

You are welcome to redistribute it under certain conditions.

Type ‘license()’ or ‘license()’ for distribution details.

Natural language support but running in an English locale

R is a collaborative project with many contributors.

Type ‘contributors()’ for more information and

‘citation()’ on how to cite R or R packages in publications.

Type ‘demo()’ for some demos, ‘help()’ for on-line help, or

‘help.start()’ for an HTML browser interface to help.

Type ‘q()’ to quit R.

>

You are now up and running with the latest version of R. The process for installation of R 3.0.x is similar for Debian and Fedora distributions. Each of these will be covered in a future tutorial.


Using R in Nonparametric Statistics: Basic Table Analysis, Part Two


Using R in Nonparametric Statistics: Basic Table Analysis, Part Two

A Tutorial by D.M. Wiig

As discussed in a previous tutorial one of the most common methods display ng and analyzing data is through the use of tables. In this tutorial I will discuss setting up a basic table using R and exploring the use of the CrossTable function that is available in the R ‘gmodel’ package. I will use the same hypothetical data table that I created in Part One of this tutorial, data that examines the relationship between income and political party identification among a group of registered voters. The variable “income” will be considered ordinal in nature and consists of categories of income in thousands as follows:

“< 25”; “25-50”; “51-100” and “>100”

Political party identification is nominal in nature with the following categories:

“Dem”, “Rep”, “Indep”

Frequency counts of individuals that fall into each category are numeric. In the first example we will create a table by entering the data as a data frame and displaying the results. When using this method it is a good idea to set up the table on paper before entering the data into R. This will help to make sure that all cases and factors are entered correctly. The table I want to generate will look like this:

party
income                Dem Rep Indep
<25 1                          5     5      10
26-50                      20    15    15
51-100                  10     20    10
>100                        5       30    10

When using the CrossTable() function the data should be entered in matrix format. Enter the data from the table above as follows:

>#enter data as table matrix creating the variable ‘Partyid’
>#enter the frequencies
>Partyid <-matrix(c(15,20,10,5, 5,15,20,30, 10,15,10,10),4,3)
>#enter the column dimension names and column heading categories
>dimnames(Partyid) = list(income=c(“<25”, “25-50″,”51-100”, “>100”), party=c(“Dem”,”Rep”,”Indep”))

To view the structue of the created data matrix use the command:

> str(Partyid)
num [1:4, 1:3] 15 20 10 5 5 15 20 30 10 15 …
– attr(*, “dimnames”)=List of 2
..$ income: chr [1:4] “<25” “25-50” “51-100” “>100”
..$ party : chr [1:3] “Dem” “Rep” “Indep”
>

To view the table use the command:

> Partyid
                                                     party
income                       Dem Rep Indep
<25                                   15     5      10
25-50                             20     15    15
51-100                         10      20   10
>100                               5        30   10
>  

Remember that R is case sensitive so make sure you use upper case if you named your variable ‘Partyid.’

Once the table has been entered as a matrix it can be displayed with a number of available options using the CrossTable() function. In this example I will produce a table in SAS format(default format), display both observed and expected cell frequencies, the proportion of the Chi-square total contributed by each cell, and the results of the chi-square analysis. The script is:
> #make sure gmodels package is loaded
> require(gmodels)
> #CrossTable analysis
> CrossTable(Partyid,prop.t=FALSE,prop.r=FALSE,prop.c=FALSE,expected=TRUE,chisq=TRUE,prop.chisq=TRUE)

Cell Contents
|—————————–|
|                                                    N |
|                             Expected N |
| Chi-square contribution |
|—————————-|
Total Observations in Table: 165
                                             | party
income | Dem | Rep | Indep | Row Total |
<25        |    15     | 5              | 10        | 30                   |
                 | 9.091 | 12.727 |8.182  |                          |
                 | 3.841 | 4.692 | 0.404 |                             |

25-50 |      20             15             | 15 |      |50

                 15.152 | 21.212 | 13.636 | |
               | 1.552   | 1.819    | 0.136 | |

51-100 | 10           | 20            | 10 |         40 |
              | 12.121 | 16.970 | 10.909 | |
|                 0.371 |   0.541 |    0.076 | |
————-|———–|———–|———–|———–|
>100 |        5 |          30             | 10 |        45 |
          | 13.636 | 19.091 |    12.273 | |
           | 5.470 |   6.234 |         0.421 | |
————-|———–|———–|———–|———–|
Column Total | 50 | 70 | 45 | 165 |
————-|———–|———–|———–|———–|
Statistics for All Table Factors
Pearson’s Chi-squared test
————————————————————
Chi^2 = 25.55608 d.f. = 6 p = 0.0002692734

>

As seen above row marginal totals and column marginal totals are displayed by default with the SAS format. There are other options available for the CrossTable() function. See the CRAN documentation for a detailed description of all of the options available. In the next installment of this tutorial I will examine some of the measures of association that are available in R for nominal and ordinal data displayed in a table format.