Tag Archives: r for beginners

Using R for Analysis of Large Text Files: Creating Comparison wordclouds


In part one of this tutorial, I discussed the use of the tm and wordcloud packages to create a visual representation of the most frequently used words in the 2026 Presidential State of the Union Address. I also discussed the code needed to generate an initial analysis of the wordcloud with a list of the 15 most used words and their frequency. I also discussed code that calculated a matrix consisting of the relative strength of association among 10 most commonly used words and other words used in the address. In this tutorial I will present code to display two wordclouds, one containing frequently used words in the 2009 State of the Union Address, and one containing the frequently used words from the 2017 State of the Union Address. I will also show the R code necessary to produce a simple bar graph of the most frequently used words and the association matrix for each wordcloud.

The required R code is essentially the same as the code used in part one of the tutorial with additional code to create the second wordcloud and associated statistics and to display the graphics side by side. I have also included a simple bar graph to display a comparison of the most frequently used words in each SOTU. As is my practice in all of my tutorials I have included a running commentary for each major section of the code. Make sure that you make the appropriate changes in your path to the SOTU files to be loaded before running the program and that all required packages are installed in your R libraries. As always, make sure that you are running up to date R-base and RStudio versions.

###################################################
#wordcloudcomp, displays sotu09 and sotu17 side by side
#calculates word counts, most frequent words, word assoc #strengths
###################################################
###################################################
#Load required packages
###################################################
install.packages(“tm”) #processes data
install.packages(“wordcloud”) #creates visual plot
install.packages(“tidyverse”) #graphics utilities
install.packages(“readr”) #to load text files
install.packages(“RColorBrewer”) #for color graphics
install.packages(“ggplot2”)
###################################################
#Read in text file for 2009 SOTU
library(readr)
statu09 <- read_table(“E:/dellfiles/statu09.txt”, col_names = FALSE)
#read in text file for 2017 SOTU
statu17 <- read_table(“E:/dellfiles/statu17.txt”, col_names = FALSE)
###################################################
#convert each text to Corpus format
#docs09 <- statu09 2009 address
#docs17 <- statu17 2017 address
###################################################
library(tm)
docs09 <- Corpus(VectorSource(statu09))
#
docs17 <- Corpus(VectorSource(statu17))
#
###################################################
#clean each file; remove punctuation, stop words, white space
#use either “en” or “SMART” predefined set for stop words #removal
###################################################
library(tm)
library(wordcloud)
#
data(docs09)
docs09 <- tm_map(docs09, function(x)removeWords(x,stopwords(“en”)))
docs09 <- tm_map(docs09,removePunctuation) #remove punctuation
docs09 <- tm_map(docs09,stripWhitespace) #remove white space
#
data(docs17)
docs17 <- tm_map(docs17,function(x)removeWords(x,stopwords(“en”)))
docs17 <- tm_map(docs17,removePunctuation) #remove punctuation
docs17 <- tm_map(docs17,stripWhitespace) #remove white space
#
###################################################
#Cleaned corpus is now formatted into text document matrix
#Then frequency count done for each word in matrix
#dmat <-create matrix; dval <-sort; dframe <-count word frequencies
###################################################
#2009 address
#
docmat09 <- TermDocumentMatrix(docs09)
dmat09 <- as.matrix(docmat09)
dval09 <- sort(rowSums(dmat09),decreasing=TRUE)
dframe09 <- data.frame(word=names(dval09),freq=dval09)
#
#2017 address
docmat17 <- TermDocumentMatrix(docs17)
dmat17 <- as.matrix(docmat17)
dval17 <- sort(rowSums(dmat17),decreasing=TRUE)
dframe17 <- data.frame(word=names(dval17),freq=dval17)
#
###################################################
#create 2 panels, each to display a wordcloud
###################################################
#
par(mfrow=c(1,2))
#
####################################################create 2009 wordcloud
###################################################
#
library(RColorBrewer)
set.seed(1234) #use if random.color=TRUE
par(bg=”white”) #background color
wordcloud(dframe09$word,dframe09$freq,colors=brewer.pal(8,”Set1″),random.order=FALSE,scale=c(2,0.35),min.freq=2,max.words=200,rot.per=0.0)
# Add a title above the plot
mtext(“SOTU 2009″, side = 3, line = 2, cex = 1.5)
#
###################################################
#create 2017 wordcloud
###################################################
#
library(RColorBrewer)
set.seed(1234) #use if random.color=TRUE
par(bg=”yellow”) #background color
wordcloud(dframe17$word,dframe17$freq,colors=brewer.pal(8,”Set1″),random.order=FALSE,scale=c(2,0.35),min.freq=2,max.words=200,rot.per=0.0)
# Add a title above the plot
mtext(“SOTU 2017”, side = 3, line = 2, cex = 1.5)
#
###################################################
#this section contains code for printing word freq tables;
#doing bar graphs of word freq; word assoc analysis;
#code to print 15 most used words with freq;
#capture output in form to copy to Tex or other editor
###################################################
#for 2017 address
out <- capture.output(head(dframe17,15))
writeLines(out)
#
###################################################
#for 2009 address
out <- capture.output(head(dframe17,15))
writeLines(out)
#
####################################################code to print simple bar graph of most frequently
#used words for each SOTU; set to show 15 words
###################################################
#for 2009 address
library(ggplot2)
#
barplot(dframe09[1:15,]$freq, las=2, names.arg = dframe09[1:15,]$word, col = “blue”)
# Add a title above the plot
mtext(“SOTU 2009 Word Frequency”, side = 3, line = 2, cex = 1.5)
#
###################################################
#for 2017 address
library(ggplot2)
#
barplot(dframe17[1:15,]$freq, las=2, names.arg = dframe17[1:15,]$word, col = “red”)
# Add a title above the plot
mtext(“SOTU 2017 Word Frequency”, side = 3, line = 2, cex = 1.5)
#
###################################################
#code to find associations among specified terms
#drops cor < .25
#initial setup for most frequent words; 10 most frequently used
###################################################
#for 2009 address
out <- capture.output((findAssocs(docmat09,terms = c(“and”,”will”,”know”,”economy”,”every”,”now”,”can”,”plan”,”but”,”economy”),corlimit = .25)))
writeLines(out)
#
#for 2017 address
out <- capture.output((findAssocs(docmat17,terms = c(“and”,”will”,”america”,”american”,”must”,”country”,”new”,”people”,”great”,”world”),corlimit = .25)))
writeLines(out)
#
######################################################################################################
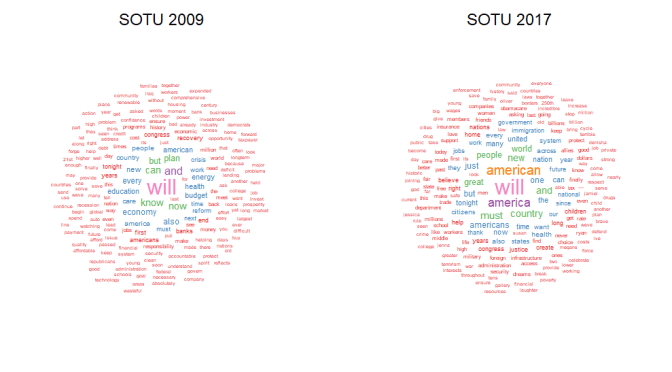
The wordclouds are seen side by side below.
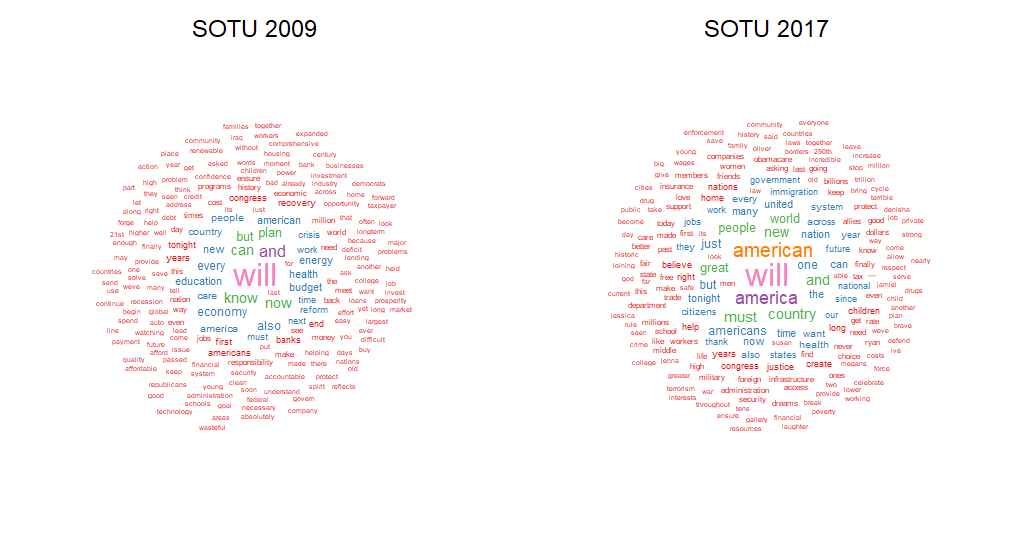

The bar graph that follows show the frequencies for the most used words in each address.
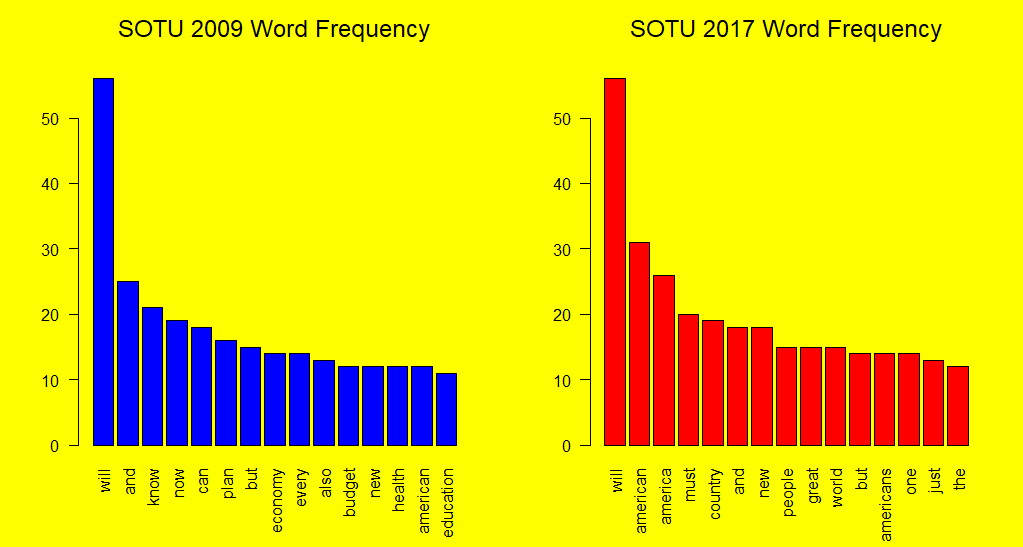

In order to save space, I have uploaded the word association matrix data for each SOTU into a markdown file that can be viewed by clicking the link at the bottom of this posting.

In parts one and two of this tutorial I focused on an approach that treats the document as a matrix of meaningful individual words. This approach is a good starting point. I will cap this approach in part three by discussing two additional wordcloud functions, the comparison.cloud and the commonality.cloud functions. In part four of this tutorial, I will present code that will allow analysis of the sentences and structure of the entire document. This will allow the use of a more advanced R package for text analysis, the contentanalysis  package.

This document .pdf click -> sotu0917

Word association matrix click ->0917assoctab

All R programming for this project was done using RStudio 2026.07.0+139 “Pacific Dogwood.”
This PDF document was produced using TeXstudio 4.9.5 (git 4.9.5)
Using Qt Version 6.11.0, compiled with Qt 6.11.0 R.
R, RStudio, and TeXstudio are free, open-source software.
R For Beginners: Basic Graphics Code to Produce Informative Graphs, Part Two, Working With Big Data


R for beginners: Some basic graphics code to produce informative graphs, part two, working with big data

A tutorial by D. M. Wiig

In part one of this tutorial I discussed the use of R code to produce 3d scatterplots. This is a useful way to produce visual results of multi- variate linear regression models. While visual displays using scatterplots is a useful tool when using most datasets it becomes much more of a challenge when analyzing big data. These types of databases can contain tens of thousands or even millions of cases and hundreds of variables.

Working with these types of data sets involves a number of challenges. If a researcher is interested in using visual presentations such as scatterplots this can be a daunting task. I will start by discussing how scatterplots can be used to provide meaningful visual representation of the relationship between two variables in a simple bivariate model.

To start I will construct a theoretical data set that consists of ten thousand x and y pairs of observations. One method that can be used to accomplish this is to use the R rnorm() function to generate a set of random integers with a specified mean and standard deviation. I will use this function to generate both the x and y variable.

Before starting this tutorial make sure that R is running and that the datasets, LSD, and stats packages have been installed. Use the following code to generate the x and y values such that the mean of x= 10 with a standard deviation of 7, and the mean of y=7 with a standard deviation of 3:

##############################################
## make sure package LSD is loaded
##
library(LSD)
x <- rnorm(50000, mean=10, sd=15)   # # generates x values #stores results in variable x
y <- rnorm(50000, mean=7, sd=3)    ## generates y values #stores results in variable y
####################################################

Now the scatterplot can be created using the code:

##############################################
## plot randomly generated x and y values
##
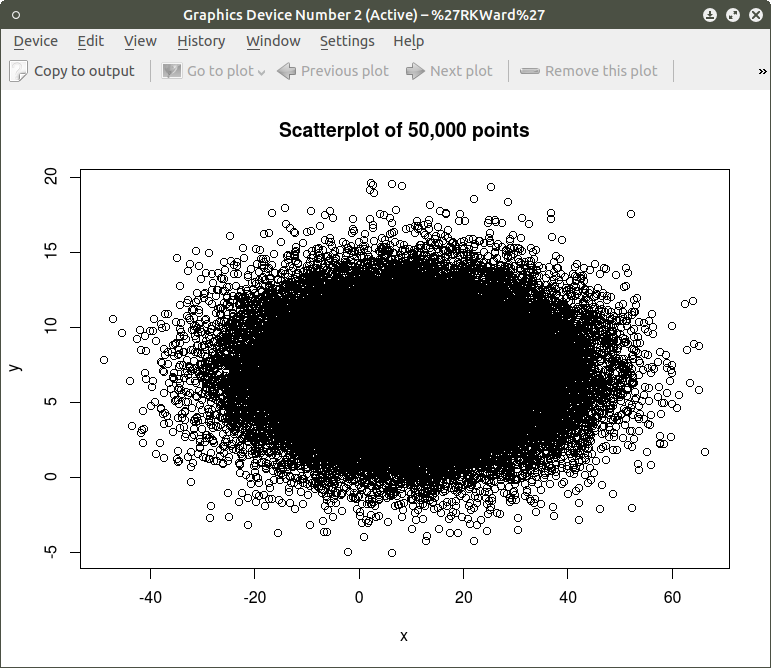
plot(x,y, main=”Scatterplot of 50,000 points”)
####################################################

screenshot-graphics-device-number-2-active-%27rkward%27

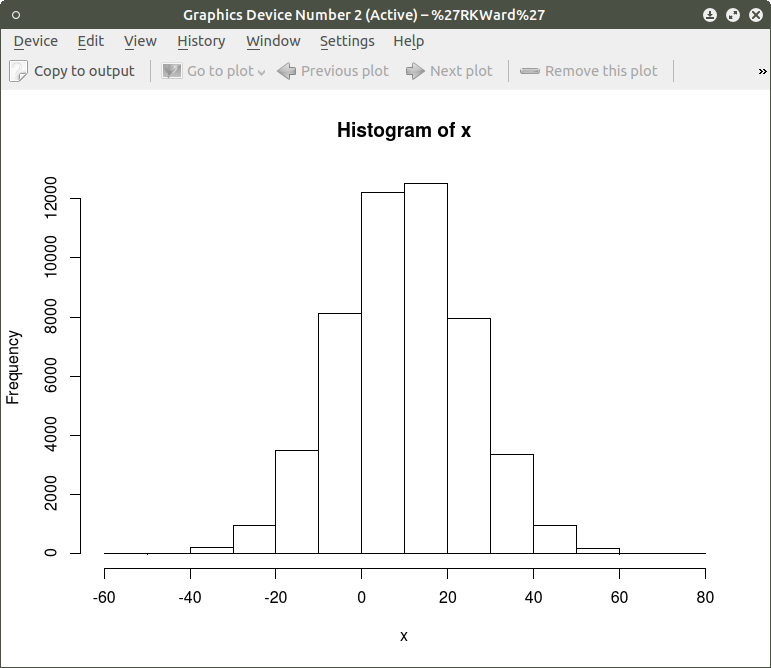
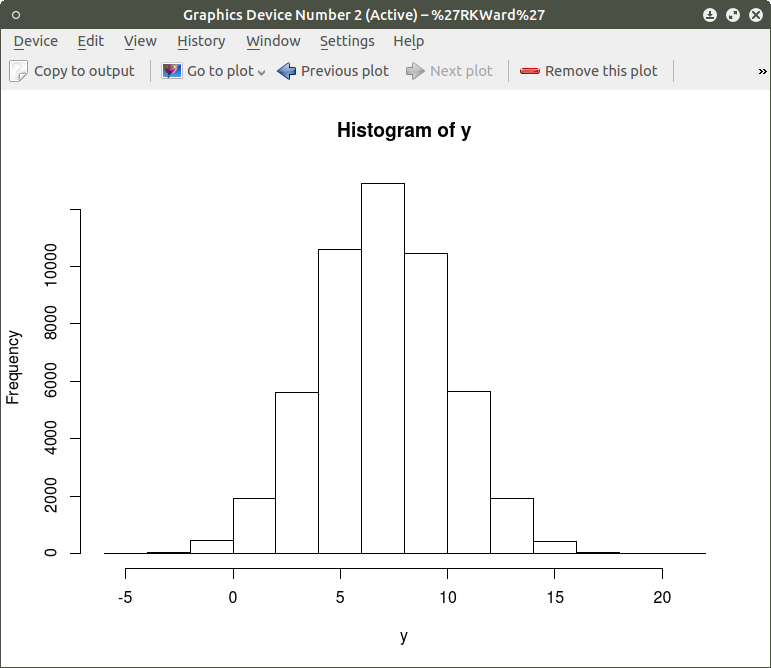
As can be seen the resulting plot is mostly a mass of black with relatively few individual x and y points shown other than the outliers.  We can do a quick histogram on the x values and the y values to check the normality of the resulting distribution. This shown in the code below:
####################################################
## show histogram of x and y distribution
####################################################
hist(x)   ## histogram for x mean=10; sd=15; n=50,000
##
hist(y)   ## histogram for y mean=7; sd=3; n-50,000
####################################################

screenshot-graphics-device-number-2-active-%27rkward%27-5

screenshot-graphics-device-number-2-active-%27rkward%27-4

The histogram shows a normal distribution for both variables. As is expected, in the x vs. y scatterplot the center mass of points is located at the x = 10; y=7 coordinate of the graph as this coordinate contains the mean of each distribution. A more meaningful scatterplot of the dataset can be generated using a the R functions smoothScatter() and heatscatter(). The smoothScatter() function is located in the graphics package and the heatscatter() function is located in the LSD package.

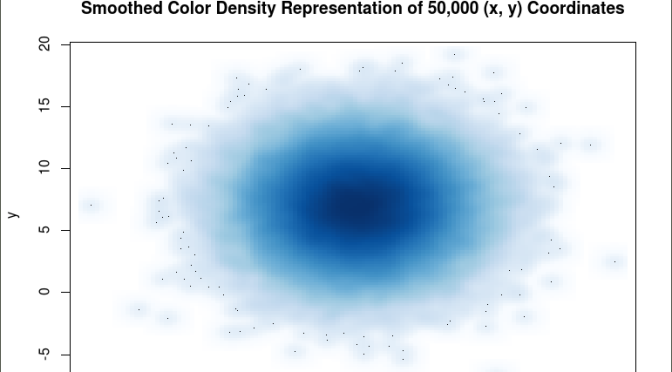
The smoothScatter() function creates a smoothed color density representation of a scatterplot. This allows for a better visual representation of the density of individual values for the x and y pairs. To use the smoothScatter() function with the large dataset created above use the following code:

##############################################
## use smoothScatter function to visualize the scatterplot of #50,000 x ## and y values
## the x and y values should still be in the workspace as #created  above with the rnorm() function
##
smoothScatter(x, y, main = “Smoothed Color Density Representation of 50,000 (x,y) Coordinates”)
##
####################################################

screenshot-graphics-device-number-2-active-%27rkward%27-6

The resulting plot shows several bands of density surrounding the coordinates x=10, y=7 which are the means of the two distributions rather than an indistinguishable mass of dark points.

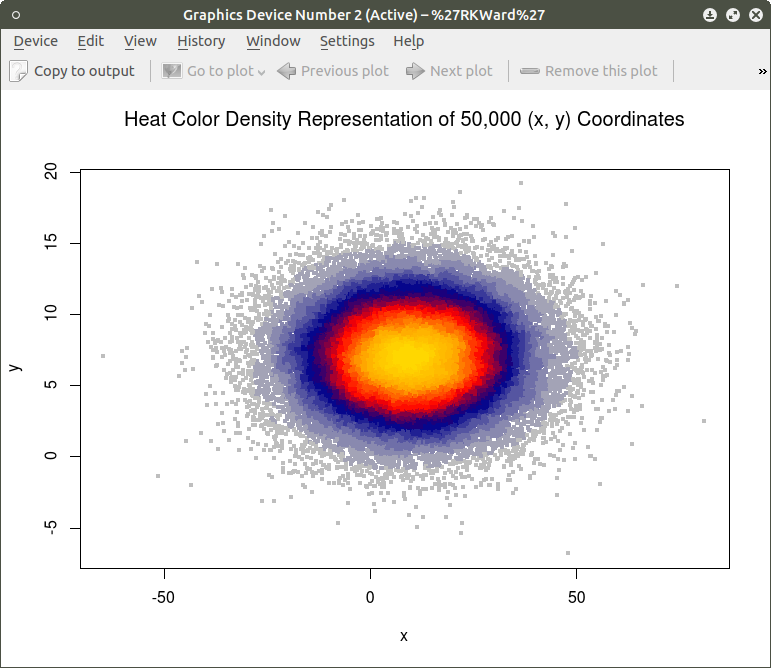
Similar results can be obtained using the heatscatter() function. This function produces a similar visual based on densities that are represented as color bands. As indicated above, the LSD package should be installed and loaded to access the heatscatter() function. The resulting code is:

##############################################
## produce a heatscatter plot of x and y
##
library(LSD)
heatscatter(x,y, main=”Heat Color Density Representation of 50,000 (x, y) Coordinates”) ## function heatscatter() with #n=50,000
####################################################

screenshot-graphics-device-number-2-active-%27rkward%27-7

In comparing this plot with the smoothScatter() plot one can more clearly see the distinctive density bands surrounding the coordinates x=10, y=7. You may also notice depending on the computer you are using that there is a noticeably longer processing time required to produce the heatscatter() plot.

This tutorial has hopefully provided some useful information relative to visual displays of large data sets. In the next segment I will discuss how these techniques can be used on a live database containing millions of cases.

R for Beginners: Some Simple Code to Produce Informative Graphs, Part One


A Tutorial by D. M. Wiig

The R programming language has a multitude of packages that can be used to display various types of graph. For a new user looking to display data in a meaningful way graphing functions can look very intimidating. When using a statistics package such as SPSS, Stata, Minitab or even some of the R Gui’s such R Commander sophisticated graphs can be produced but with a limited range of options. When using the R command line to produce graphics output the user has virtually 100 percent control over every aspect of the graphics output.

For new R users there are some basic commands that can be used that are easy to understand and offer a large degree of control over customisation of the graphical output. In part one of this tutorial I will discuss some R scripts that can be used to show typical output from a basic correlation and regression analysis.

For the first example I will use one of the datasets from the R MASS dataset package. The dataset is ‘UScrime´ which contains data on certain factors and their relationship to violent crime. In the first example I will produce a simple scatter plot using the variables ‘GDP’ as the independent variable and ´crimerate´ the dependent variable which is represented by the letter ‘y’ in the dataset.

Before starting on this project install and load the R package ‘MASS.’ Other needed packages are loaded when R is started. The scatter plot is produced using the following code:

####################################################
### make sure that the MASS package is installed
###################################################
library(MASS)   ## load MASS
attach(UScrime)   ## use the UScrime dataset
## plot the two dimensional scatterplot and add appropriate #labels
#
plot(GDP, y,
main=”Basic Scatterplot of Crime Rate vs. GDP”,
xlab=”GDP”,
ylab=”Crime Rate”)
#
####################################################

The above code produces a two-dimensional plot of GDP vs. Crimerate. A regression line can be added to the graph produced by including the following code:

####################################################
## add a regression line to the scatter plot by using simple bivariate #linear model
## lm generates the coefficients for the regression model.extract
## col sets color; lwd sets line width; lty sets line type
#
abline(lm(y ~ GDP), col=”red”, lwd=2, lty=1)
#
####################################################

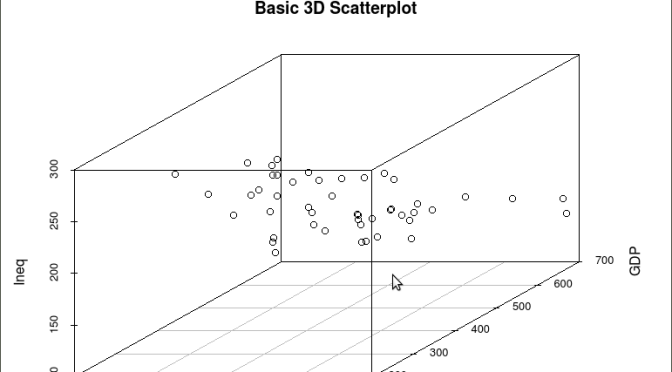
As is often the case in behavioral research we want to evaluate models that involve more than two variables. For multivariate models scatter plots can be generated using a 3 dimensional version of the R plot() function. For the above model we can add a third variable ‘Ineq’ from the dataset which is a measure the distribution of wealth in the population. Since we are now working with a multivariate linear model of the form ‘y = b1(x1) + b2(x2) + a’ we can use the R function scatterplot3d() to generate a 3 dimensional representation of the variables.

Once again we use the MASS package and the dataset  ‘UScrime’ for the graph data. The code is seen below:

####################################################
## create a 3d graph using the variables y, GDP, and Ineq
####################################################
#
library(scatterplot3d)   ##load scatterplot3d function
require(MASS)
attach(UScrime)   ## use data from UScrime dataset
scatterplot3d(y,GDP, Ineq,
main=”Basic 3D Scatterplot”) ## graph 3 variables, y
#
###################################################

The following graph is produced:

screenshot-graphics-device-number-2-active-%27rkward%27

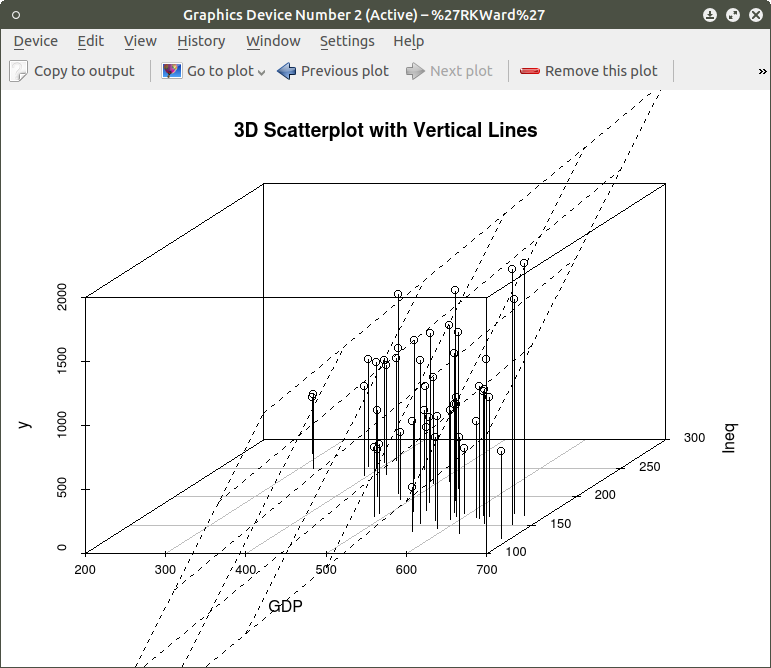
The above code will generate a basic 3d plot using default values. We can add straight lines from the plane of the graph to each of the data points by setting the graph type option as ‘type=”h”, as seen in the code below:

##############################################

require(MASS)
library(scatterplot3d)
attach(UScrime)
model <- scatterplot3d(GDP, Ineq, y,
type=”h”, ## add vertical lines from plane with this option
main=”3D Scatterplot with Vertical Lines”)
####################################################

This results in the graph:

screenshot-graphics-device-number-2-active-%27rkward%27-1

There are numerous options that can be used to go beyond the basic 3d plot. Refer to CRAN documentation to see these. A final addition to the 3d plot as discussed here is the code needed to generate the regression plane of our linear regression model using the y (crimerate), GDP, and Ineq variables. This is accomplished using the plane3d() option that will draw a plane through the data points of the existing plot. The code to do this is shown below:

##############################################
require(MASS)
library(scatterplot3d)
attach(UScrime)
model <- scatterplot3d(GDP, Ineq, y,
type=”h”,   ## add vertical line from plane to data points with this #option
main=”3D Scatterplot with Vertical Lines”)
## now calculate and add the linear regression data
model1 <- lm(y ~ GDP + Ineq)   #
model$plane3d(model1)   ## link the 3d scatterplot in ‘model’ to the ‘plane3d’ option with ‘model1’ regression information
#
####################################################

The resulting graph is:

screenshot-graphics-device-number-2-active-%27rkward%27-2

To draw a regression plane through the data points only change the ‘type’ option to ‘type=”p” to show the data points without vertical lines to the plane. There are also many other options that can be used. See the CRAN documentation to review them.

I have hopefully shown that relatively simple R code can be used to generate some informative and useful graphs. Once you start to become aware of how to use the multitude of options for these functions you can have virtually total control of the visual presentation of data. I will discuss some additional simple graphs in the next tutorial that I post.

R For Beginners: Basic R Code for Common Statistical Procedures Part I


An R tutorial by D. M. Wiig

This section gives examples of code to perform some of the most common elementary statistical procedures. All code segments assume that the package ‘car’ has been loaded and the file ‘Freedman’ has been loaded as the active dataset. Use the menu from the R console to load the ’car’ dataset or use the following command line to access the CRAN site list and packages:


install.packages()

Once the ’car’ package has been downloaded and installed use the following command to make it the active library.

require(car)

Load the ‘Freedman’ data file from the dataset ‘car’

data(Freedman, package="car")

List basic descriptives of the variables:

summary(Freedman)

Perform a correlation between two variables using Pearson, Kendall or Spearman’s correlation:

cor(filename[,c("var1","var2")], use="complete.obs", method="pearson")

cor(filename[,c("var1","var2")], use="complete.obs", method="spearman")

cor(filename[,c("var1","var2")], use="complete.obs", method="kendall")

Example:

cor(Freedman[,c("crime","density")], use="complete.obs", method="pearson")

cor(Freedman[,c("crime","density")], use="complete.obs", method="kendall")

cor(Freedman[,c("crime","density")], use="complete.obs", method="spearman")

In the next post I will discuss basic code to produce multiple correlations and linear regression analysis.  See other tutorials on this blog for more R code examples for basic statistical analysis.


R Video Tutorial: Basic R Code to Load a Data File and Produce a Histogram


R For Beginners:  Some Simple R Code to Load a Data File and Produce a Histogram

A tutorial by D. M. Wiig

I have found that a good method for learning how to write R code is to examine complete code segments written to perform specific tasks and to modify these procedures to fit your specific needs. Trying to master R code in the abstract by reading a book or manual can be informative but is more often confusing.  Observing what various code segments do by observing the results allows you to learn with hands-on additions and modifications as needed for your purposes.

In this document I have included a short video tutorial that discusses  loading a dataset from the R library, examining the contents of the dataset and selecting one of the variables to examine using a basic histogram.  I have included an annotated code chunk of the procedures discussed in the video.

The video appears below with the code segment following.

Here is the annotated code used in the video:

###################################
#use the dataset mtcars from the ‘datasets’ package
#select the variable mpg to do a histogram
#show a frequency distribution of the scores
##########################################
#library is ‘datasets’
#########################################
library(“datasets”)
#########################################
#take a look at what is in ‘datasets’
#########################################
library(help=”datasets”)
#######################################
#take a look at the ‘mtcars’ data
#########################################
View(mtcars)
#######################################
#now do a basic histogram with the hist function
###########################################
hist(mtcars$mpg)
#############################################
#dress up the graph; not covered in the video but easy to do
############################################
hist(mtcars$mpg, col=”red”, xlab = “Miles per Gallon”, main = “Basic Histogram Using ‘mtcars’ Data”)
###################################################


R For Beginners: A Video Tutorial on Installing and Using the Deducer Statistics Package


R For Beginners:  A Video Tutorial on Installing and Using the Deducer Statistics Package with the R Console

In previous tutorials I have discussed the use of R Commander and Deducer statistical packages that provide a menu based GUI for R.  In this video tutorial I will discuss downloading and installing the Deducer statistics package.  This video is designed to support my previous tutorial on the same subject.

I have embedded the video below,   I hope you find this tutorial  a useful adjunct to installing and using the menu based Deducer package.

This document is an embedded Word document.  To view it full screen click on the icon in the lower right corner of the screen


R For Beginners: Installing the latest version of R on a Linux platform


R for Beginners:  Installing the latest version of R on a Linux platform

A tutorial by D. M. Wiig

One of the nice characteristics of open source software such as R is the rapid development of new releases and updates.  While the base core remains stable for a period of time there is a considerable amount of updating,  adding, and removing the component packages.  At the time of this writing the latest iteration is R version 3.3.1, “Bug in Your Hair.” If you are using a Windows platform you will likely go directly to the archive web site and download the latest distribution as a Windows executable installation package.

If you are using a Linux distribution  such as Ubuntu or Debian, the process of adding software is usually accomplished via the menu based installer.  These software installers allow  R and its dependencies to be downloaded from the community archive.

One of the disadvantages of using this approach is that the versions of some software in the archives may not be updated to the latest version.  This is often the case with R.

To insure that you are downloading the latest R version you need to use the platform’s command line to install what is needed.  Regradless of which Linux distribution you are using first open a command console from the desktop menu. Make sure all is up to date by using the command:

pi@raspberrypi:~ $ sudo apt-get update
This will insure all appropriate packages currently installed are running the latest updates.  If you are running a Debian distribution such as jessie you will need to edit the /etc/apt/sources.list file to add a backport to the latest version of R.  Use the nano editor by using the command:

sudo nano /etc/apt/sources.list

This should produce the output as seen below:

pi@raspberrypi:~ $ sudo nano /etc/apt/sources.list

------------------------------------------------
GNU nano 2.2.6 File: /etc/apt/sources.list

deb http://mirrordirector.raspbian.org/raspbian/ jessie main contrib non-free r$
# Uncomment line below then 'apt-get update' to enable 'apt-get source'
deb-src http://archive.raspbian.org/raspbian/ jessie main contrib non-free rpi
deb http://archive.raspbian.org/raspbian/ stretch main
deb http://mirror.las.iastate.edu/CRAN/bin/linux/debian/ jessie main
deb http://mirror.las.iastate.edu/CRAN/bin/linux/ubuntu xenial/

[ Read 8 lines ]
^G Get Help ^O WriteOut ^R Read File ^Y Prev Page ^K Cut Text ^C Cur Pos
^X Exit ^J Justify ^W Where Is ^V Next Page ^U UnCut Text^T To Spell


If you are using a Debian distribution you would add the line to the file

http://mirror.las.iastate.edu/CRAN/bin/linux/debian/ jessie main

Replace the mirror portion with <URL of your favorite CRAN mirror>.  Replace the 'jessie' portion with the name of the specific Debian distribution you are using.

If you are using an Ubuntu distribution add a line with the appropriate changes for the specific Ubuntu distribution that you are using.

Once these changes are made exit the nano editor using the ^O key command to write the file and then the ^X key command to return to the command line.  You should now be able to issue the command:

pi@raspberrypi:~ $ sudo apt-get install r-base r-base-core r-base-dev

Once the download and install processes have completed you should now be able to invoke R from the command line or menu and see the latest version:

pi@raspberrypi:~ $ R

R version 3.3.2 RC (2016-10-23 r71578) -- "Sincere Pumpkin Patch"
Copyright (C) 2016 The R Foundation for Statistical Computing
Platform: arm-unknown-linux-gnueabihf (32-bit)

R is free software and comes with ABSOLUTELY NO WARRANTY.
You are welcome to redistribute it under certain conditions.
Type 'license()' or 'licence()' for distribution details.

 Natural language support but running in an English locale

R is a collaborative project with many contributors.
Type 'contributors()' for more information and
'citation()' on how to cite R or R packages in publications.

Type 'demo()' for some demos, 'help()' for on-line help, or
'help.start()' for an HTML browser interface to help.
Type 'q()' to quit R.

> 


For other Linux distributions you would add a line similar to the above examples in the /etc/apt/sources.list. Check the documentation for your specific Linux platform for further information.


R Video Tutorial For Beginners: Installing And Using the Rcommander GUI


R Video Tutorial For Beginners: Installing And Using the Rcommander GUI

A tutorial video by D. M. Wiig

In my recent series of tutorials for those interested in the R statistical programming language I have discussed both the installation and use of the R console and R Commander statistics GUI.  Before viewing the tutorial make sure the R Commander package has been download into your R library via the Install Packages menu option.  This procedure was discussed in the previously posted R Commander tutorial.

Relative to this first tutorial I have have created a video that covers the initial installation of R Commander.  The video is seen below:

Click the icon in the lower right side of the screen to view the tutorial in full screen mode.

I hope that you find this useful in your pursuit of learning about  R statistics.

R for Beginners: Using R Commander in an Introductory Statistics Course


R for beginners:  Using R Commander in introductory statistics courses

A tutorial by D. M. Wiig

As with previous tutorials in this series this document is an embedded Word documents.  To view the document full screen click on the icon in the lower right corner of the window.

R for Beginners: Using R Commander for Basic t Tests and One Way ANOVA


R for Beginners:  Using R Commander for Basic t Tests and One Way ANOVA

A tutorial by D. M. Wiig

This post is contained in an embedded Word document.  To read it full screen click on the icon in the lower right corner of the document window.

I hope that you found this tutorial informative.  Stop back by to check for new installments.  I have many currently in the writing stage.